The temptation is obvious: the model is good at writing SQL, so hand it a connection and let it work. The problems show up in week two. A revenue figure that disagrees with the finance dashboard because the assistant added a different column. A join through the wrong key that quietly doubled the rows. A confident answer about customer tier, which does not exist.
This post is about the mechanism, not the pitch — what the assistant is actually given, what it is structurally unable to do, and where the design still depends on a person getting something right.
What the assistant is given
Not a connection. Not a schema. Not rows. It is given a catalogue: the dimensions and metrics your model declares, each with a business name, a type, a format, a description and the other words people use for it.
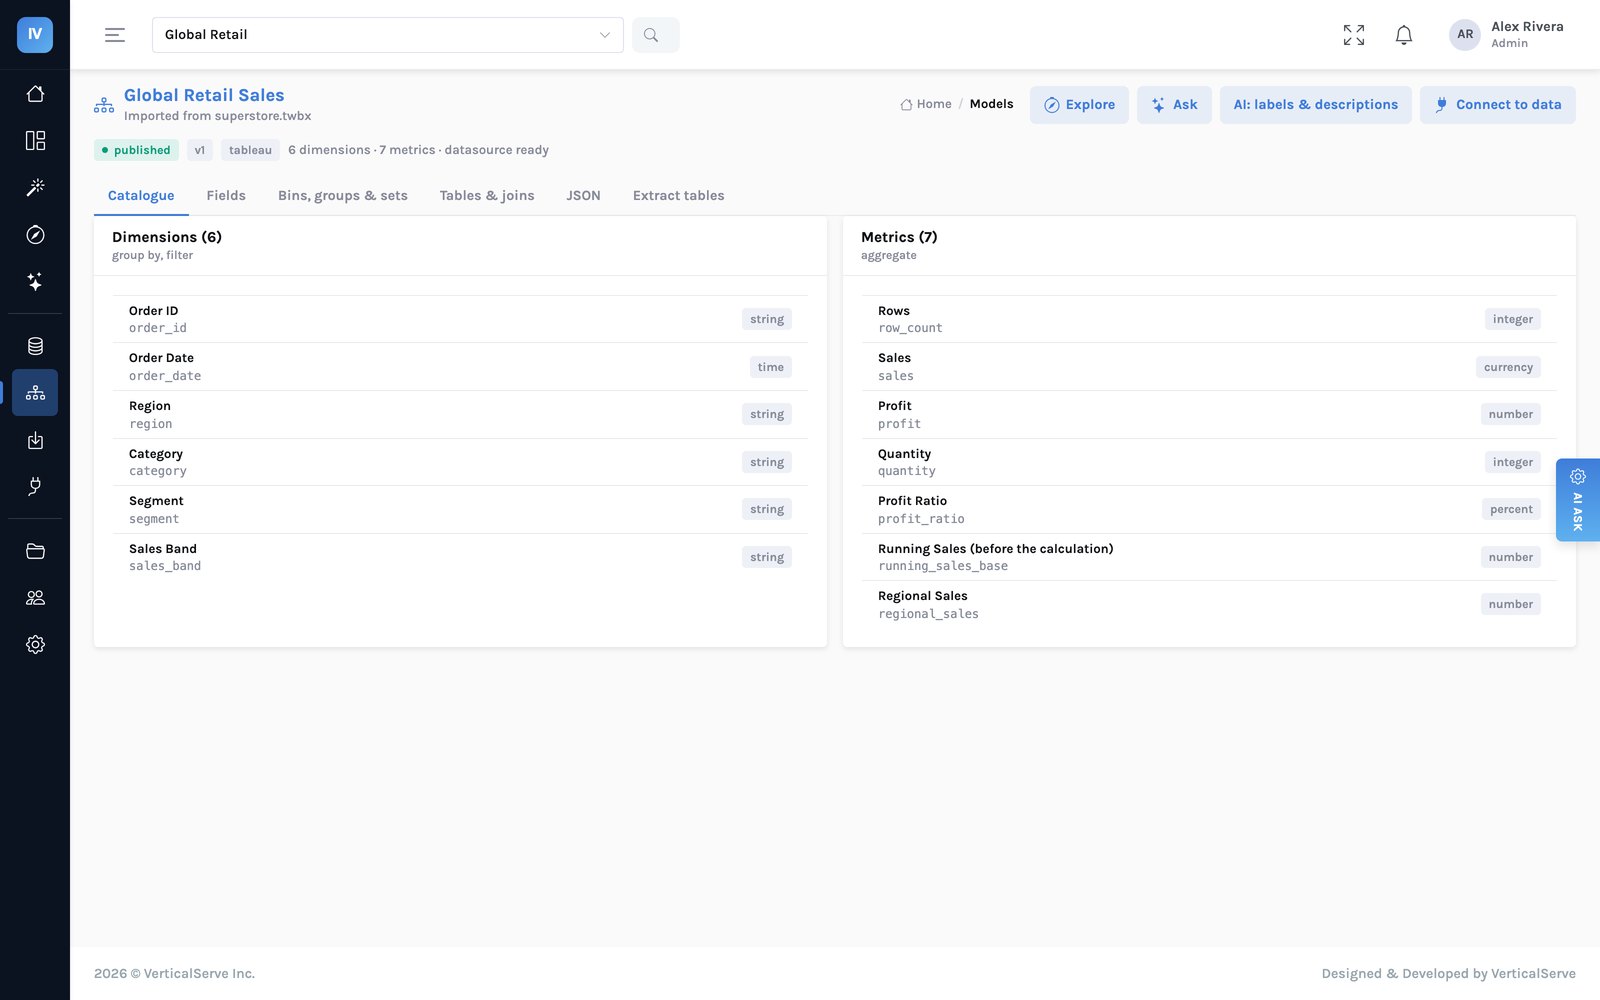
Its job is to choose from that list and say how to slice it. The output is not SQL — it is a logical query, which is a small structured object naming metrics, dimensions, filters and a limit.
Every join, aggregation and column name is a decision made in the moment against a schema. A wrong decision still produces valid SQL, still runs, and still returns a number.
The model picks from a fixed vocabulary. The compiler — ordinary, deterministic code — turns that into SQL using joins a person declared once.
sankey-beta
Columns in the warehouse,Never modelled,358
Columns in the warehouse,In the model,62
In the model,Hidden by a column policy,7
In the model,Visible to this person,55
Visible to this person,What the assistant may name,55
The compiler, not the model, writes the SQL
This is the load-bearing part. Between the assistant's choice and the database sits a compiler that knows the model's tables, its declared joins, its grain and the person's access rules. It is deterministic: the same logical query produces the same SQL every time, and can be tested like any other function.
flowchart TD
    Q[""Which region has the
weakest profit ratio?""] --> A["Assistant
picks from the catalogue"]
    A --> LQ["Logical query
metrics: profit_ratio
dimensions: region"]
    LQ --> V{"Every name checked
against the catalogue"}
    V -->|"not found"| X["Refused and named"]
    V -->|"found"| C["Compiler
declared joins, model grain"]
    C --> POL["Row rules → WHERE
Column rules → removed"]
    POL --> SQL["SQL"]
    SQL --> E["Engine"]
    E --> R["Rows + chart + the query, shown"]
    style A fill:#eef1ff,stroke:#c7cdf2
    style C fill:#eef1ff,stroke:#c7cdf2
    style POL fill:#fff4e6,stroke:#f0cb9a
    style X fill:#fdecec,stroke:#eab6b6
    style R fill:#e6f7f2,stroke:#9fd8c9
So the three failure modes close like this:
| The failure | Why it cannot happen here |
|---|---|
| The wrong join | The assistant never chooses a join. Relationships are declared once in the model and the compiler applies them, pulling in only the tables a query actually needs. |
| A different definition | Net revenue exists once, as a metric. The dashboard and the answer reference the same object, so they cannot disagree. If it is wrong, it is wrong in one place. |
| An invented field | Every name in the logical query is checked against the catalogue before anything runs. A name that is not there is refused and reported, not guessed at. |
Refusing well is a feature, not a fallback
The interesting case is not the question that works. It is the question that cannot be answered — because that is where a system either says so or quietly makes something up, and one of those is unrecoverable for trust.
Asked about a field the model does not have, the answer is that the model has no such field, naming it. Asked for a column the person is not entitled to, the request is refused and the refusal is written to the audit log.
An assistant that is confidently wrong once will not be trusted again, whatever it does for the rest of the year. Refusing is cheaper than being impressive.
Access rules are applied in the same place
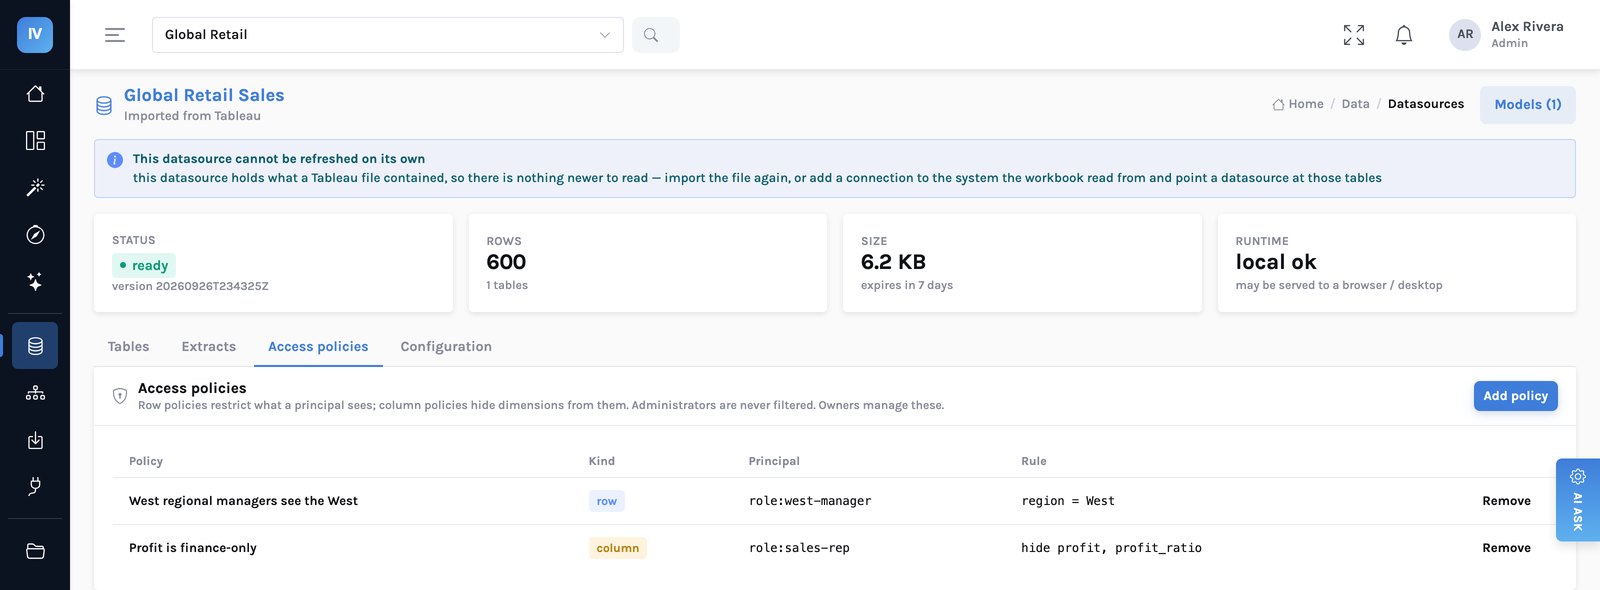
Row and column policies are not a filter over the results. They are part of the compilation. A row policy becomes a clause in the WHERE; a column policy removes the dimension from the catalogue before the assistant ever sees it.
A detail that turned out to matter
The cached result of a panel is keyed on the SQL and its bound values — and the person's policies are already inside that SQL. Two people with different access therefore compute different keys and can never be served one another's numbers. The security property falls out of the design rather than needing a separate check that someone could forget.
Where this design still depends on people
Three honest dependencies. The mechanism removes a class of failure; it does not remove judgement.
- The joins must be declared correctly, once. The assistant cannot pick a wrong join, but it also cannot notice that the one a person declared is wrong. That error moves from the model to the modeller — which is the right place for it, because it is now in one reviewable object rather than spread across forty workbooks.
- The definitions must be agreed. Point this at three conflicting notions of net revenue and it will consistently use whichever one got written down. Consistency is not correctness.
- The catalogue has to be good. Sparse descriptions and missing synonyms produce a weaker assistant, because matching a question to a field is genuinely the part the model does. This is unglamorous work and it is the highest-leverage hour anyone spends.
The same rule, one step further: the sentence
The mechanism above bounds the query: the model can only ask for what the catalogue has. It says nothing about the sentence the model writes afterwards, and that is where a plausible number gets invented. So the same rule is now applied there too. When a model writes a summary — of an answer, or of the explanation behind a chart — every figure in it is pulled out and traced back to the rows it was given: a cell, a total, a share, a difference or a ratio between named rows. A figure that traces is marked; one that does not is reported, and a summary carrying one is not shown.
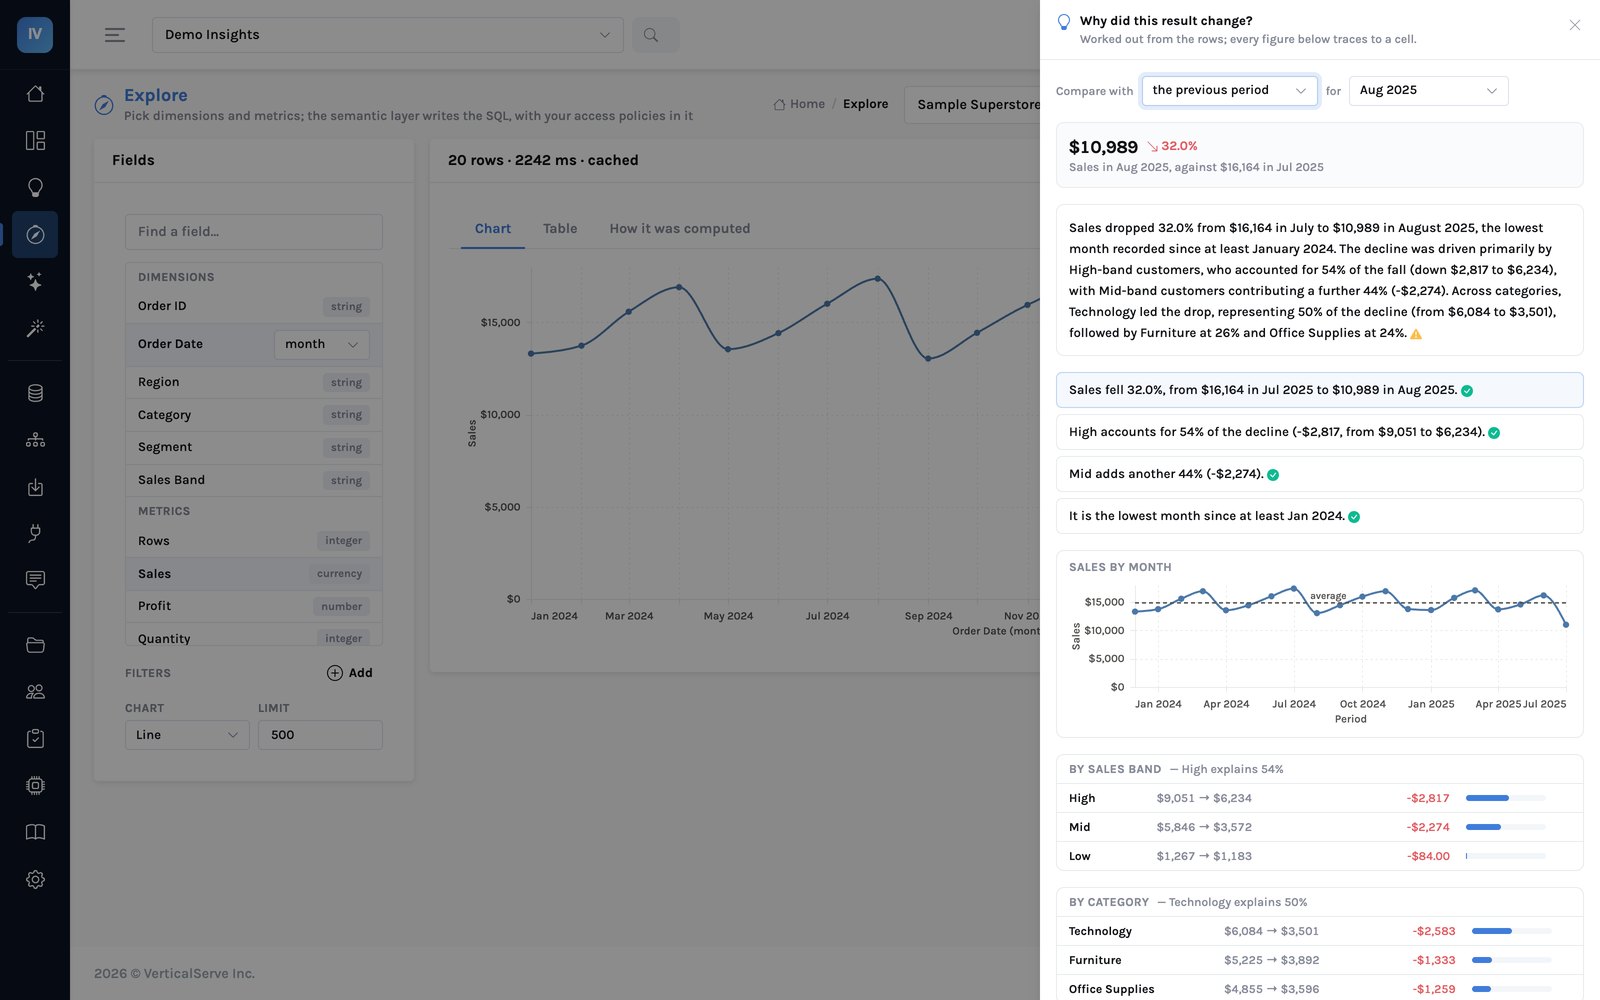
This check asks no model anything — it is arithmetic over the rows, the same kind of ordinary, tested code as the compiler. It is what lets the explanation sit in front of a finance director rather than in front of an analyst who verifies it. The explanation, worked through →
Why every answer shows its working
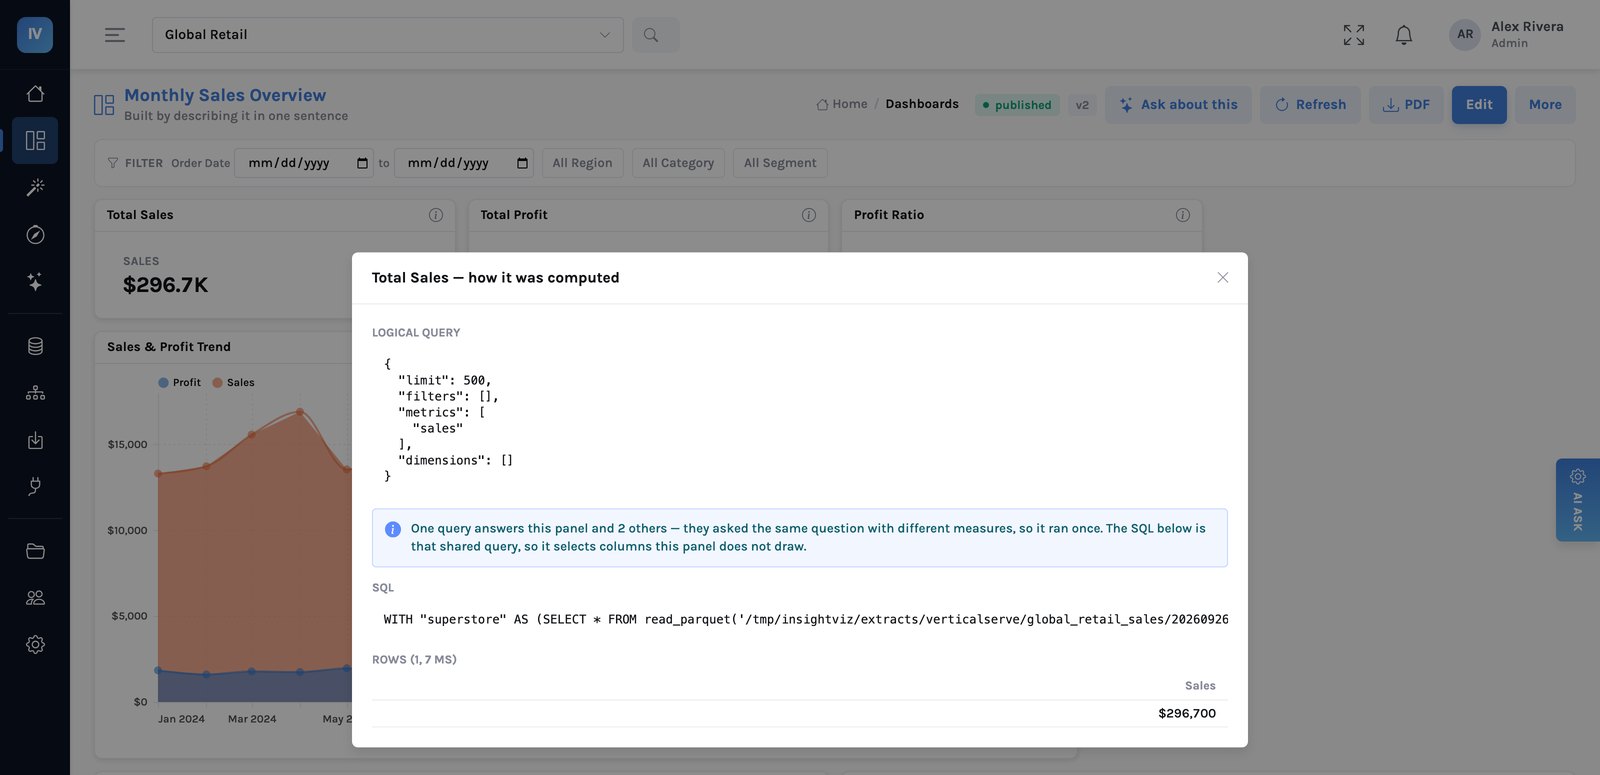
Because the mechanism above is a claim, and a claim needs evidence a reader can check without asking the person who built it. Every answer and every panel will show the logical query, the SQL and the rules that applied.
What this changes in an organisation → · Why the definitions disagree in the first place →